I have both platform.deepseek.com (hooray off-peak pricing) and the $100/m Claude subscription and boy do I find myself mostly using DS-flash pretty much every time.
There's something to be said for the speed with which it gets word done - I take fewer "it's compiling" breaks, and lose my train of thought less frequently. What's crazy is that the speedy work it does is pretty much always correct - which is a reason why I don't feel the need to spin up claude-code and "ask the expert".
This speed & good-work combo is the DS signature IMO
I use DS-4.1-Flash a lot but find it often gets caught up in long thinking runs. The "But wait... Actually... Hmm..." type of thing. Even though the tok/s is good, it stills feels slow because of this. Same with 1017.
I use Opus 5.5 at work and it does this much less (I know, different classes). Maybe it is to be expected of the flash models.
Which claude model are you comparing it to? If you're using fable max obv it's going to be slower, but like sonnet high is both faster and more intelligent
I live in the US right now, my surface of attack from the US govt & ad companies is infinitely larger even if I decide to move to China some time in the future
> I'd rather my data go to China and directly to labs that release open weight models (DeepSeek is MIT licensed still); instead of closed labs and the NSA/CIA; who has far better ability to hurt me than China does.
Thank you. I've been shouting this very obvious thing from rooftops
I work in silicon valley and I feel everyone around me is suffering from China-BAD psychosis and dismiss Chinese releases
I have both platform.deepseek.com (hooray off-peak pricing) and the $100/m Claude subscription and boy do I find myself mostly using DS-flash pretty much every time.
There's something to be said for the speed with which it gets word done - I take fewer "it's compiling" breaks, and lose my train of thought less frequently. What's crazy is that the speedy work it does is pretty much always correct - which is a reason why I don't feel the need to spin up claude-code and "ask the expert".
This speed & good-work combo is the DS signature IMO
OpenAI subscriptions are shit tier. Deepseek does 90% of what I need to do for pennies. There is no comparison. And I’m talking about working on relatively hard domain like gpu kernel optimisation and HPC
Or just us Europeans who are so sick of American corporations milking every penny with their LLM models and preventing us from using the full model capabilities.
Now we have: a ton of competition in different inference providers, very low costs, and speeds reaching 1k tok/s in certain providers.
We can just get a box of compute even in Germany, and run the exact same model here without anybody stopping us.
What would you prefer, 30t/s 50k output tokens needed for solution, or 300t/s, 500k output tokens needed for solution?
This is why "tokens per second" alone is a deeply flawed comparator.
This is also why discussions of Chinese models focus on tokens per second- they struggle to compete on intelligence so they dramatically increase effort levels to compensate, meaning they require massive total output tokens.
For example, flash 1017 isn't benchmarked yet, but 0731 required 15.4M tokens to complete the artificial analysis benchmark, and Sol 6.1 high required just 2.8M.
I certainly don't think the self-reported single benchmark scores are the best way to answer the question. I waited for the Artifical Analysis run (which itself is still mediocre, but at least it's an order of magnitude better), and predictably the results tell a different story.
Sol 6.1 High: 50 intelligence, $0.32 per task, 4.4 min per task, 13k output tokens per task
Sol 6.1 Medium: 48 intelligence, $0.21 per task, 2.9 min per task, 8k output tokens per task
Deepseek 4.1 1017: 45 intelligence, $0.26 per task, 4.8 min per task, 89k output tokens per task
If you look at the actual pareto frontier across the full benchmark, Sol 6.1 remains firmly on the pareto line, while deepseek remains firmly under it, just as it was before https://i.imgur.com/N72p5NF.png
This result is exactly as I expected, and seems to run counter to the effusive praise of this thread. Sol 6.1 Medium is producing higher quality output at a lower price with nearly 10X less output tokens! And this is not surprising.
And finally, Mimo V2.6 Pro continues to look like a stunning release, clearly smarter, cheaper and faster than deepseek v4.1 1017
"Sol 6.1 Medium is producing higher quality output ..." -- When it is actually up and working. Even last night I still received constant capacity messages halting codex over a dozen times and I gave up and shut the workflows down.
I would prefer it work and solve quicker. Opus 5.5 has a reasonable pace to me. Sol does not. I understand efficiency I just don't like using it right now because it has literally hung or failed to complete tasks a dozen times in the last week due to inference capacity.
If you don't buy into "America good, China bad" narrative, this new entrant & release by Inclusion Ai is a lot more exciting by every measurable metric.


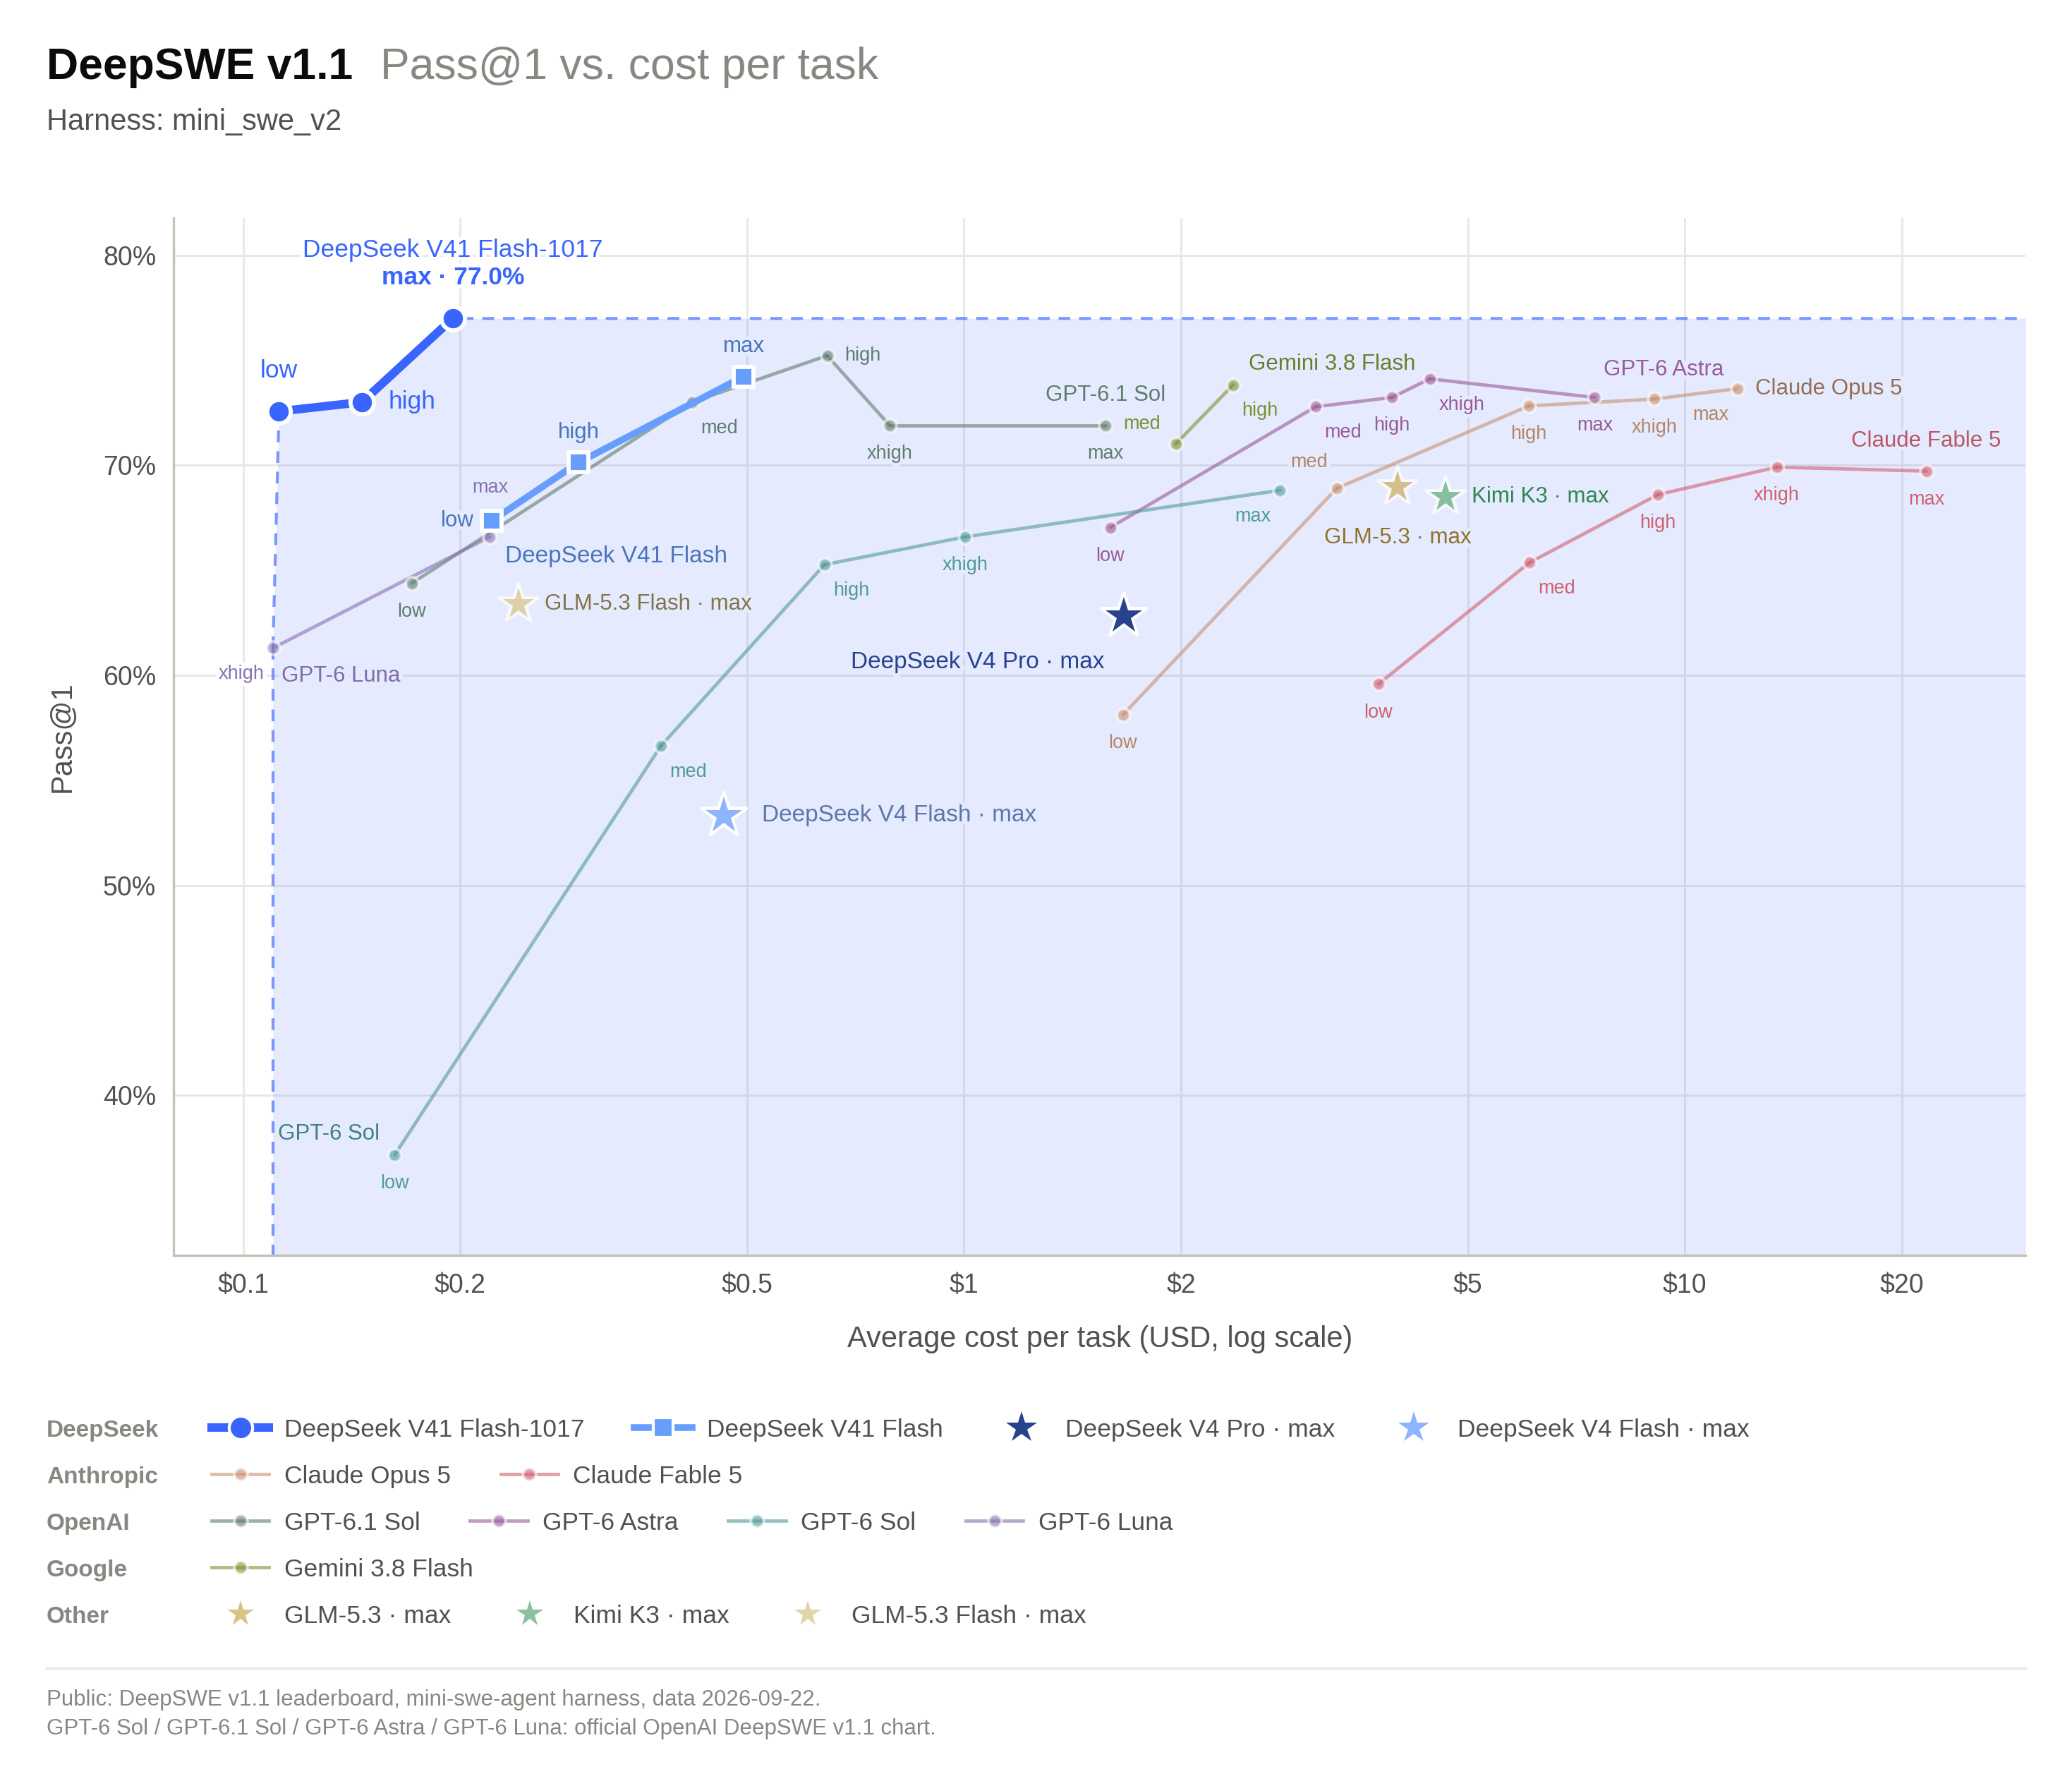

I have both platform.deepseek.com (hooray off-peak pricing) and the $100/m Claude subscription and boy do I find myself mostly using DS-flash pretty much every time.
There's something to be said for the speed with which it gets word done - I take fewer "it's compiling" breaks, and lose my train of thought less frequently. What's crazy is that the speedy work it does is pretty much always correct - which is a reason why I don't feel the need to spin up claude-code and "ask the expert".
This speed & good-work combo is the DS signature IMO
reply